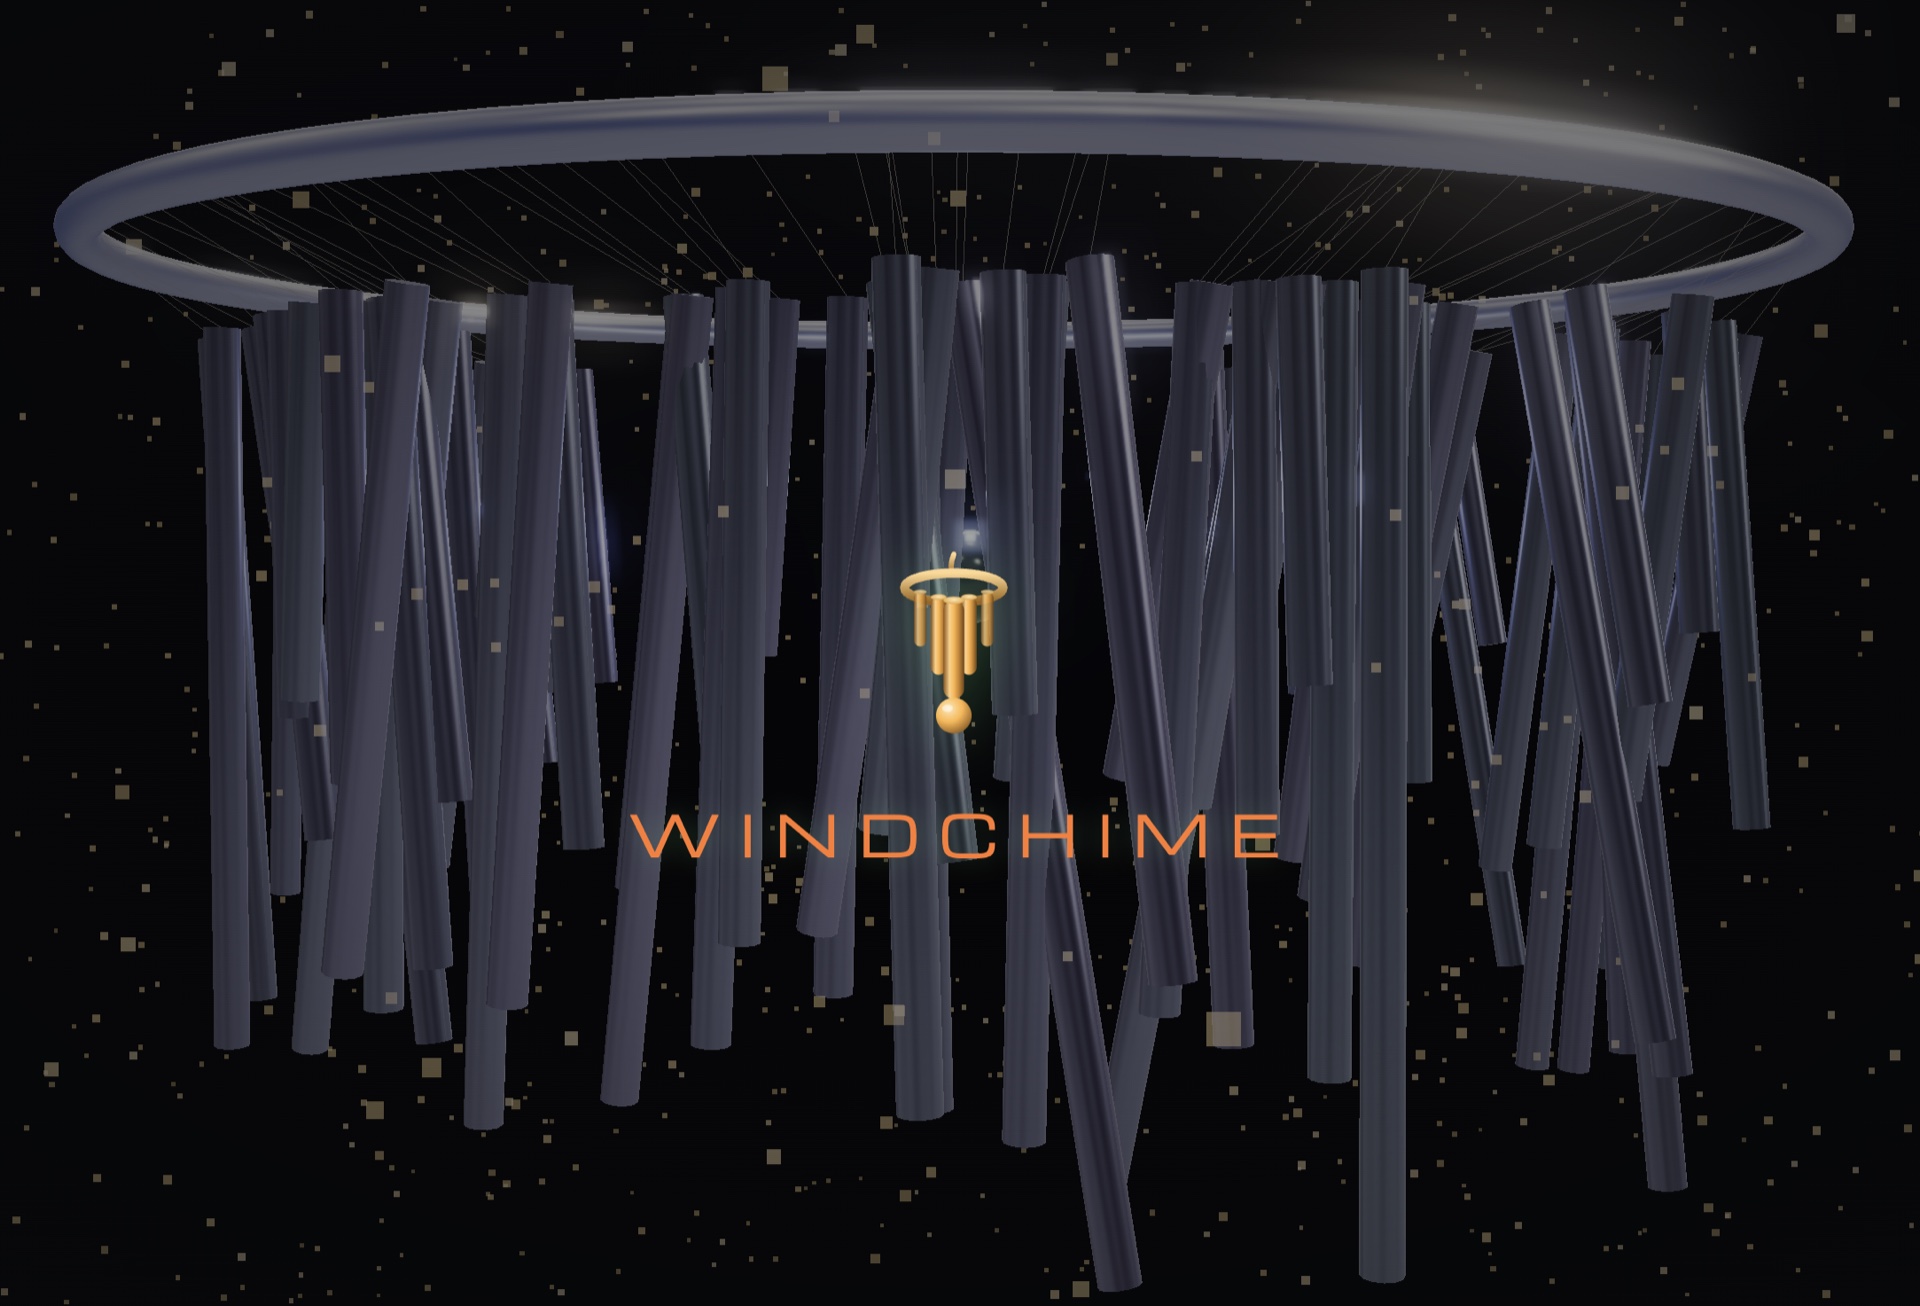
Windchime

Details
Shown at Gray Area, San Francisco; accepted to NeurIPS 2026 Creative AI, Sydney Paper coauthored with Celeste Betancur, CCRMA, Stanford University.
Audio language models retrieve real stems from a closed, artist authored corpus and render them as live coded sound, generative visuals and monome light.
Languages PythonTypeScriptJavaScriptp5.jsThree.jsStrudel (pattern DSL)HTML/CSSShell
Core skills Audio language models (CLAP, CLaMP 3) Speech recognition (faster-whisper) Vector retrieval (FAISS) Live coded audio (Strudel) Generative visuals (p5.js, Three.js) Hardware control (monome) Offline, unattended deployment
May 2026 to present